Predictive modeling uses observed data and statistical or machine-learning methods to estimate an unknown or future outcome. A useful model must perform well on new cases, and its predictions shouldn’t be mistaken for proof of cause.
A technology employer might already have a recruiting dashboard, a growing backlog of applications, and pressure to fill critical roles. The harder question isn’t what happened last month. It’s where recruiters should focus attention next, whether engineering demand will outpace capacity, and whether a prediction provides enough evidence to act.
Table of Contents
- Predictive Modeling in Everyday Decisions
- How Predictive Models Learn From Data
- Choosing Common Predictive Modeling Approaches
- Building a Predictive Modeling Workflow
- Evaluating Predictions Before Deployment
- Hiring and HR Analytics Use Cases
- Decide When Predictive Modeling Is Appropriate
- Keep Predictive Models Useful After Launch
Predictive Modeling in Everyday Decisions
A recruiting manager sees several open engineering positions and uneven candidate engagement. Historical reports describe completed interviews and accepted offers, but the manager needs to anticipate upcoming workload. A predictive model could estimate application volume or the likelihood that an active candidate progresses to another stage.
The basic mechanism is straightforward: a model learns relationships between input variables and a target variable, then applies those relationships to new cases. That definition, including the distinction between explaining an outcome and predicting it, sits within the statistical foundations of predictive modeling.
Three Different Analytical Questions
| Question type | Core question | Example | What the answer does not establish |
|---|---|---|---|
| Descriptive | What happened? | Which recruiting stages had the longest delays? | What will happen next |
| Predictive | What outcome is likely? | Which open roles may take longer to fill? | Which intervention would shorten hiring |
| Causal | What would change the outcome? | Would a different interview process reduce delays? | Whether the effect transfers to every setting |
The same distinction applies outside recruiting. An infrastructure team might estimate failure risk, while an operations manager forecasts demand. In each case, the prediction is an estimate, not an instruction.
Start with the decision, not the score
The operational question should come first: what could someone do differently after receiving the prediction? An application-volume forecast might support recruiter scheduling, while a system-risk estimate might prompt inspection.
Related fields, including computer vision applications, can provide inputs or estimates for business workflows. The important boundary is the same: recognizing a pattern doesn't determine the appropriate response.
Practical rule: A prediction deserves attention when an accountable person can connect it to a feasible decision.
For employers asking what is predictive modeling, this is the most useful mental model: it's a structured estimate that supports judgment, not a replacement for judgment.
How Predictive Models Learn From Data
Consider a simplified weather-forecast analogy. Historical examples contain observations such as temperature, humidity, and the weather that followed. Training means finding a reusable relationship between the available observations and the outcome being estimated.
Business models use the same basic structure. The terminology matters because misunderstandings about inputs and outcomes can undermine a project before algorithm selection begins.
- Features are the input variables examined by the model.
- The target is the value or category the model estimates.
- Training examples pair historical inputs with known outcomes.
- Generalization means applying the learned relationships successfully beyond those examples.
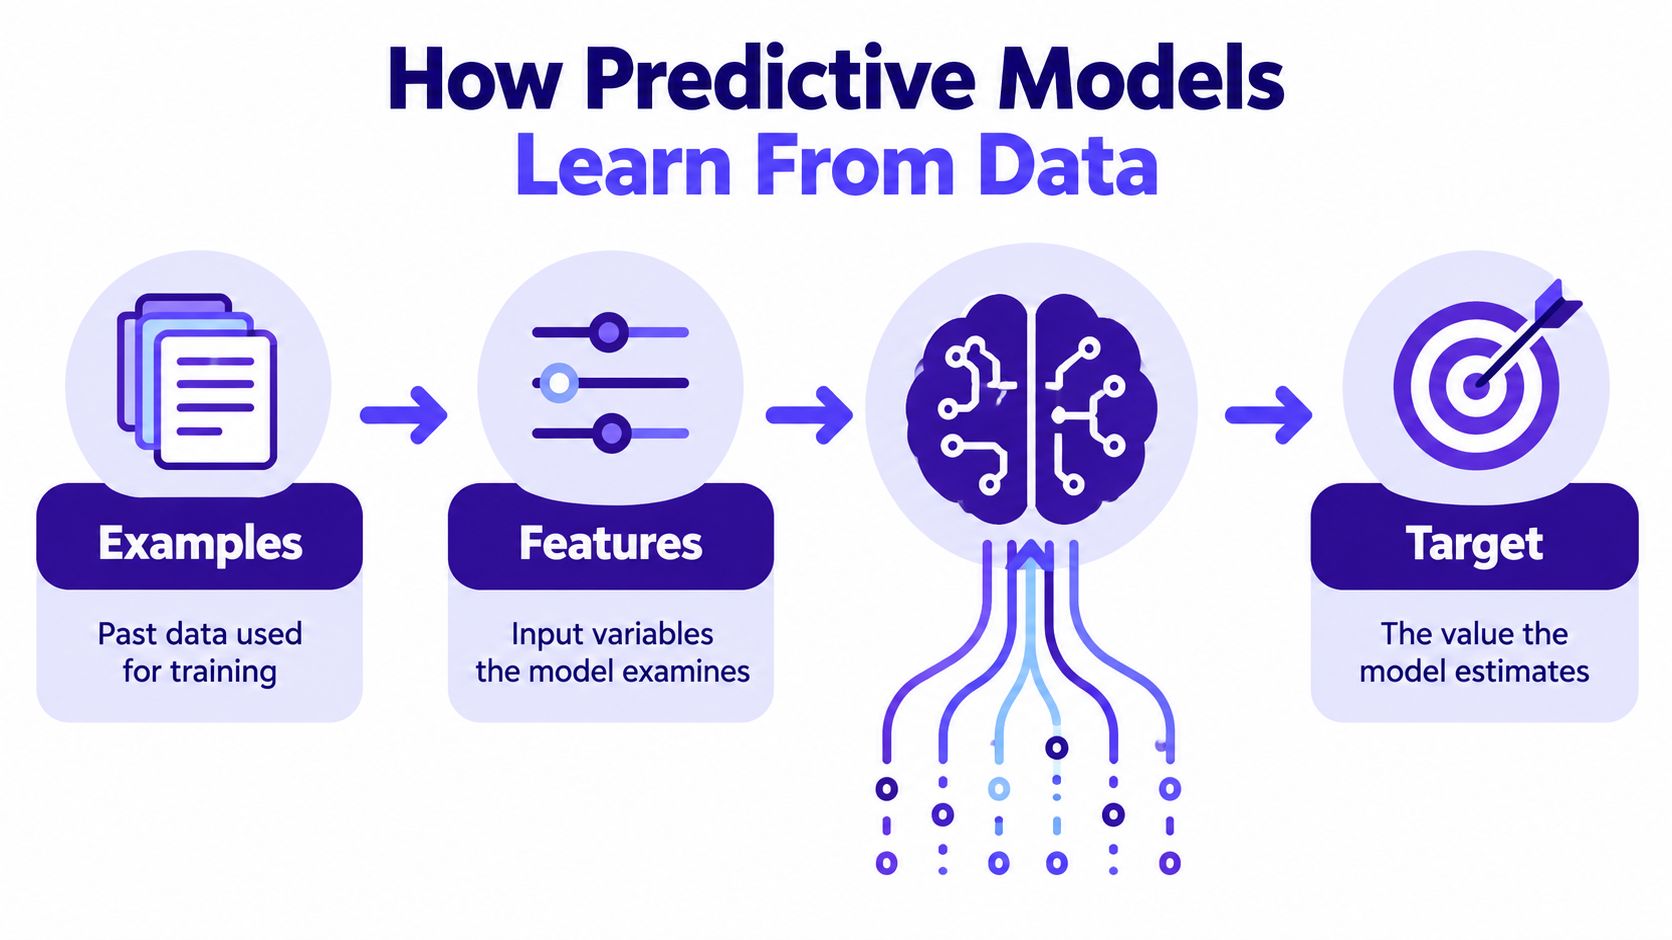
For a hypothetical recruiting-planning model, features might include role specialization, location, and the current pipeline stage. The target might be the remaining time until a role is filled. The intended output would support workload planning, not automatically judge an applicant's suitability.
The target defines the assignment
A model trained to estimate candidate progression is answering a different question from a model estimating application volume. Even when both use recruiting records, their outputs shouldn't be treated as interchangeable.
Target selection also requires business judgment. A convenient historical label may reflect an old process rather than the outcome an employer values. Teams should define what the target means before treating it as a measure of success.
Predictive modeling has roots in regression, classification, and actuarial risk estimation, as described in the statistical foundations above. Contemporary machine learning extends that older objective rather than replacing it with an entirely different purpose.
Equipment reliability offers another useful learning context. Forge Reliability's predictive maintenance machine learning guide provides a related resource for readers considering how operational observations connect to a maintenance prediction.
The central learning task remains unchanged: find relationships that travel beyond the records used during training. Memorizing yesterday's examples isn't enough.
Choosing Common Predictive Modeling Approaches
Algorithm selection should begin with the shape of the answer. Estimating a quantity, assigning a category, and forecasting an ordered sequence require different starting points.
A useful kickoff discussion separates those tasks before debating model complexity. A team estimating time to fill needs a numerical output; a team flagging possible withdrawal needs a category or probability.
Predictive Approach Selection Guide
| Analytical need | Common approach | Useful intuition | Trade-off to consider |
|---|---|---|---|
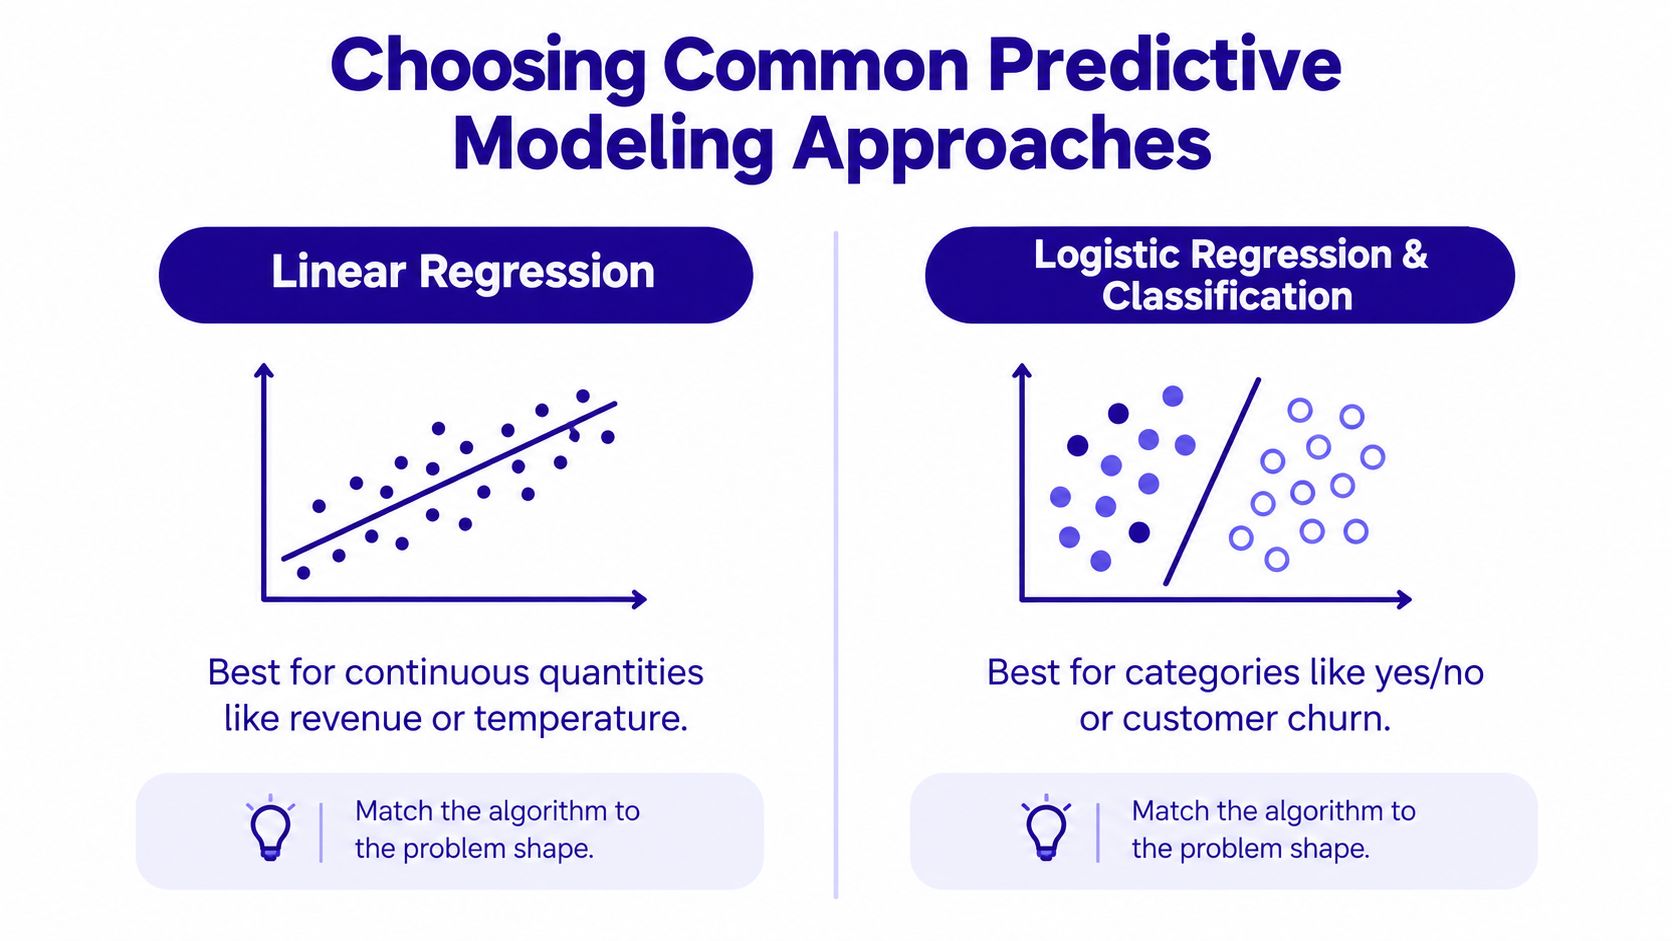
| Estimate a continuous quantity | Linear regression | Combine inputs into a numerical estimate | Whether a simple relationship is adequate |
| Estimate a category or event probability | Logistic regression or another classifier | Separate likely outcomes using observed inputs | How probabilities become operational decisions |
| Represent nonlinear patterns and interactions | Tree-based methods | Follow branching conditions through combinations of inputs | Complexity and explanation requirements |
| Forecast outcomes ordered over time | Time-series methods | Use the sequence and timing of observations | Whether historical timing patterns remain relevant |
Choose the simplest credible starting point
Linear regression is a sensible candidate when the target is a continuous quantity and a relatively straightforward relationship is plausible. Logistic regression, despite its name, belongs in a classification discussion when the intended estimate concerns an event or category.
Tree-based approaches give teams another way to represent conditional patterns. For example, a relationship might differ by role family or operational context rather than following the same pattern everywhere. A time-series approach instead makes chronological structure central to the problem.
These are selection starting points, not guarantees. The team still needs to consider available examples, missing information, implementation constraints, and the level of explanation required by reviewers.
A shared understanding of machine learning fundamentals helps hiring managers discuss those choices without turning the kickoff into an algorithm contest. The most revealing question is often whether a more complicated approach would change a real decision.
A complex model should earn its place through relevant evidence, not through the sophistication of its name.
Employers should ask candidates to explain why they would reject an approach, not merely why they would use it. That answer reveals whether the practitioner understands the assignment’s constraints.
Building a Predictive Modeling Workflow
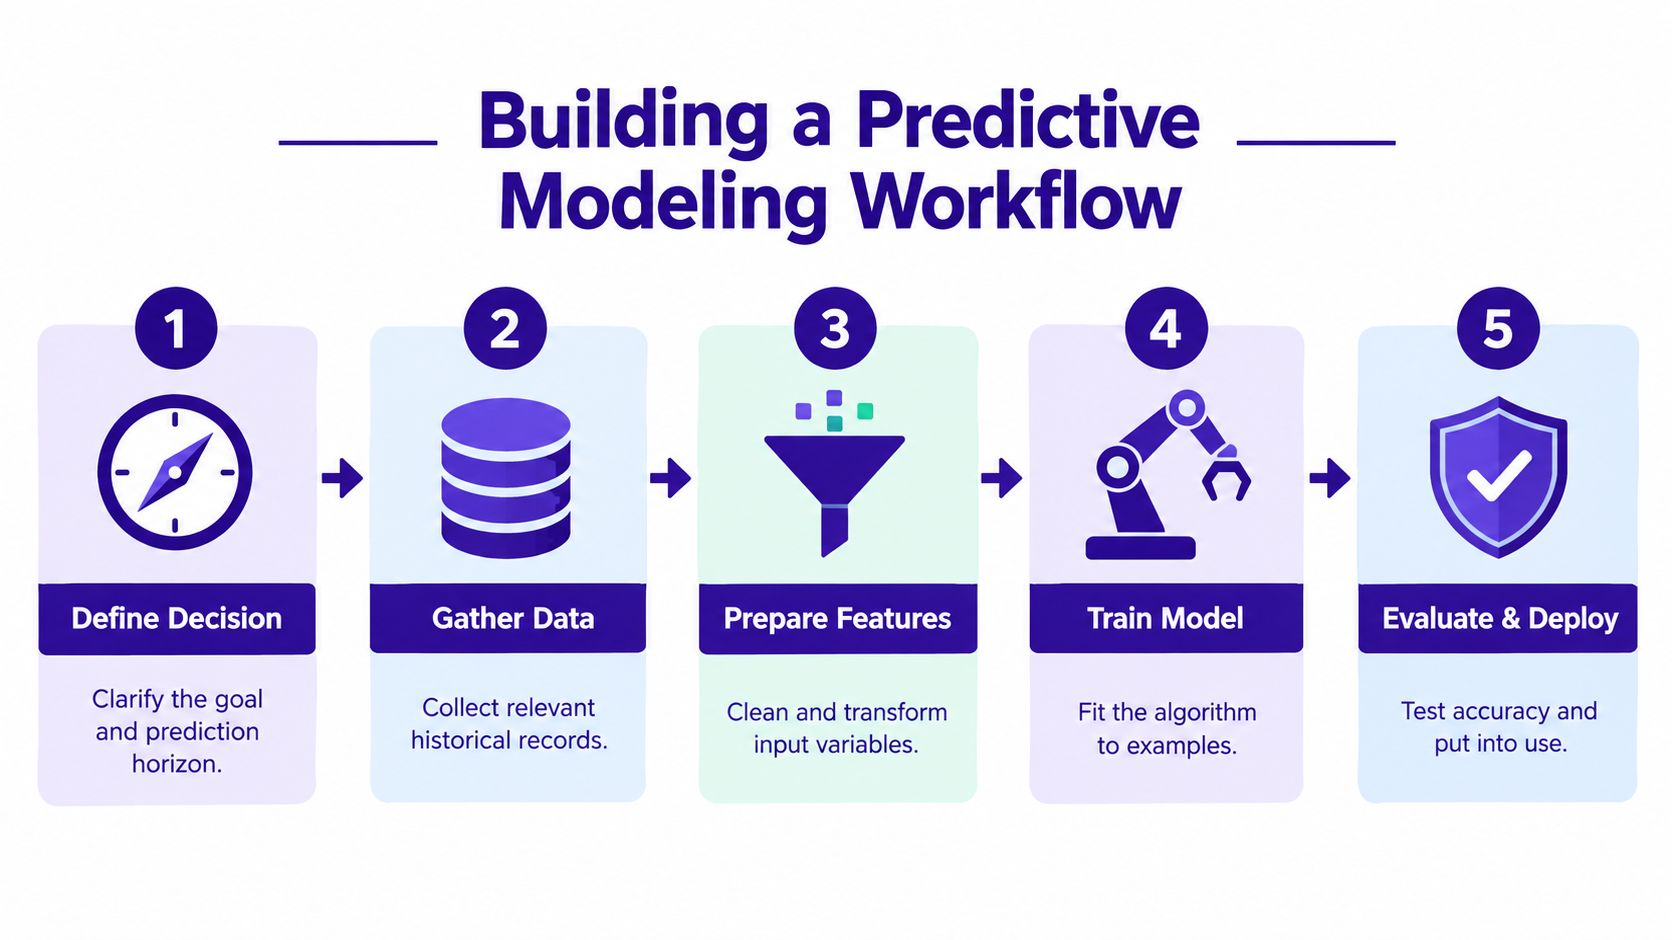
A workable modeling project begins with a written decision statement. For a recruiting-capacity forecast, that statement should identify who will use the estimate, how far ahead the forecast must reach, and which staffing decisions remain available at that point.
Acceptable errors belong in this discussion. Overestimating workload and underestimating workload may lead to different consequences, so the team shouldn’t postpone that conversation until a model has been trained.
Define and prepare before fitting
- Specify the outcome. Define the target, prediction horizon, eligible records, and intended action.
- Inspect the records. Check missing values, inconsistent definitions, duplicate entries, and whether outcome labels mean the same thing across teams.
- Explore the data. Examine distributions and unusual cases with operational specialists before transforming inputs.
- Prepare features. Use information that would exist when the prediction is made.
That final preparation rule prevents data leakage. A field recorded only after a hiring outcome, for example, shouldn’t help predict that earlier outcome. Otherwise, the development exercise gives the model information unavailable during real use.
Separate development from final judgment
Teams should reserve an untouched test set before making tuning decisions. Within the development data, k-fold cross-validation trains on all but one fold, validates on the remaining fold, and repeats until each fold has served as validation; the scikit-learn cross-validation documentation explains this separation from final testing.
Cross-validation helps compare development choices. The final test answers a different question: how does the selected approach perform on records that didn’t guide those choices?
Deployment planning should accompany development rather than follow it as an afterthought. Teams need an input contract, a destination for predictions, an accountable user, and a documented response when required information is missing.
A useful project artifact is a short decision record connecting each choice to its reason. That record should explain why the target was selected, which inputs were excluded, and what evidence would stop deployment. It gives reviewers something more actionable than a notebook containing a fitted model.
Evaluating Predictions Before Deployment
Suppose a platform team uses predictions to prioritize system inspections. An unnecessary inspection consumes capacity, while a missed failure could leave a serious issue unaddressed. Those consequences make a single headline score an incomplete basis for approval.
Evaluation should reflect the cost of mistakes, not just their count. Reviewers need to see what happens when the operating threshold changes and whether the team has enough capacity to respond to the resulting alerts.
Evaluation Questions by Prediction Task
| Prediction task | Primary evaluation question | Metrics to consider | What to inspect alongside the score |
|---|---|---|---|
| Classification | Which events are identified or missed? | Precision, recall, false-positive and false-negative rates | Alert volume and consequences of each error |
| Continuous estimation | How far are estimates from outcomes? | Mean absolute error, root mean squared error | Large misses and systematic overestimation |
| Probability estimation | Do probabilities match observed outcomes? | Calibration measures and calibration plots | Reliability across risk ranges |
| Time-series forecasting | How well are later periods predicted? | Forecast error measured on later observations | Timing, changing conditions, and forecast horizon |
Evaluate the deployment situation
Precision concerns how often flagged cases are genuine, while recall concerns how many genuine cases are captured. Regression measures instead summarize the distance between numerical estimates and observed outcomes. Calibration addresses whether a predicted probability corresponds to what subsequently happens.
For time-ordered business data, chronological validation is often more appropriate than a random split because a random split can let future information influence evaluation of the past. The train-test split and cross-validation teaching materials explain that deployment-oriented distinction.
SourceX’s guide to how evaluation holdouts work is an additional resource for teams formalizing their review process. The practical requirement is an evaluation design that resembles the conditions under which the prediction will be used.
Reviewers should also compare the model with a simple baseline, such as an existing rule or historical benchmark. Subgroup checks should examine whether acceptable overall performance conceals weak results for particular roles, locations, or operating conditions.
Approval should require both credible predictive performance and a workable response process. A technically promising score isn’t sufficient if the people receiving the output can’t use it responsibly.
Hiring and HR Analytics Use Cases
A talent-acquisition leader planning engineering recruitment could use separate estimates for application volume, candidate progression, and expected time to fill. Each would support a different operational choice, such as recruiter allocation, outreach scheduling, or coordination with hiring managers.
These are planning scenarios, not evidence that an employer should automate selection. A forecast can support a conversation about capacity without determining whether a particular person deserves an interview.
Keep risk estimates separate from treatment decisions
Attrition illustrates the boundary clearly. An accurate model may identify employees at risk without establishing which action would change their outcome, because correlations can reflect confounding, reverse causation, selection effects, or measurement artifacts, as discussed in research on moving from prediction toward intervention.
A manager shouldn’t assume that a prominent feature identifies a remedy. A relationship between an employee characteristic and departure risk doesn’t, by itself, justify changing that characteristic or treating the employee differently.
Responsible HR Modeling Questions
| Before deployment | During validation | Before acting |
|---|---|---|
| Is the target relevant to a legitimate planning need? | Does performance differ across relevant groups? | Can a reviewer explain the proposed action? |
| Could sensitive attributes enter directly or through proxies? | Do historical labels reflect past selection practices? | Could the action disadvantage an individual? |
| Is there enough relevant outcome information? | Do results remain credible under current recruiting conditions? | Is there an appropriate review or escalation route? |
Employers should scrutinize proxy risk rather than assuming that removing a sensitive field settles the issue. They should also ask whether the available labels describe all relevant applicants or only people who advanced through an earlier process.
Paradigm International Inc. on predictive HR offers a related resource for HR planning discussions. Employers considering AI for talent acquisition should define human-review boundaries before connecting predictions to candidate-facing actions.
A responsible pilot keeps the operational purpose narrow, documents permitted uses, and gives reviewers authority to question the output.
Decide When Predictive Modeling Is Appropriate
Not every uncertainty warrants a predictive system. If a fixed policy determines the answer, a rule may be clearer. If leaders need to understand a backlog, a descriptive dashboard may be sufficient.
The decision turns on whether a prediction would improve an available action enough to justify development and ongoing operation. That assessment should include the people who will use the output, not only the people proposing to build it.
Predictive Model Fit Test
| Decision check | Proceed when | Pause or change approach when |
|---|---|---|
| Data quality | Inputs and outcomes have usable, consistent definitions | Records are incomplete or meanings differ across teams |
| Repeatability | Similar decisions recur | The situation is exceptional and poorly represented |
| Feedback latency | Outcomes become available in time for evaluation | The team can’t establish whether predictions were useful |
| Error costs | Mistakes have understood consequences | Material harms remain undefined |
| Interpretability | Reviewers can obtain the explanation the workflow requires | The output can’t support meaningful scrutiny |
| Governance | An owner can approve, challenge, and suspend use | Responsibility is fragmented or absent |
Choose a method that answers the actual question
An organization trying to estimate the effect of a new outreach strategy needs more than a forecast of who will respond. Depending on feasibility and assumptions, a randomized experiment or causal-inference approach may better address the intervention question. Uplift modeling is another approach to consider when the objective is estimating differences in response to treatment.
Those alternatives shouldn't become automatic recommendations either. Teams need to assess whether experimentation is appropriate, whether necessary assumptions are defensible, and whether the available observations support the intended conclusion.
Decision boundary: Predictive accuracy is evidence about an estimate, not automatic evidence that a proposed action will work.
A practical kickoff should end with a clear disposition: proceed with modeling, simplify to a benchmark, gather better information, or choose a different analytical method. Pausing is a valid outcome when the decision lacks a usable target or a responsible owner.
Employers evaluating technical talent can use the same test in interviews. A strong practitioner should be comfortable recommending a dashboard or experiment instead of a model when that better serves the business question.
Keep Predictive Models Useful After Launch
Deployment isn't the finish line. Once a model enters a business process, its owners must determine whether the conditions supporting its use still hold.
Concept drift concerns changes in the relationship between inputs and outcomes. Monitoring and response procedures are necessary because historical relationships may no longer remain valid for new observations, as described in research on drift detection and adaptive learning.
Production Monitoring Checklist
| Monitor | Why it matters | Possible response |
|---|---|---|
| Input distributions and missingness | Incoming records may differ from development data | Investigate upstream changes or repair inputs |
| Prediction performance | Previously acceptable errors may increase | Recalibrate, retrain, or suspend use |
| Subgroup results | Aggregate measures may conceal localized problems | Investigate affected groups and restrict use |
| Prediction and alert volume | The operational workload may become unsuitable | Review thresholds and response capacity |
| Data and model versions | Reviewers need reproducible records | Restore a known version and document changes |
| Incidents and overrides | Users may identify failures absent from routine metrics | Escalate, investigate, and update procedures |
Assign ownership before an incident
NIST identifies persistent monitoring challenges including data drift, changing conditions, limited transparency, resource requirements, and organizational incentives in its guidance on monitoring deployed AI systems. Employers should treat monitoring as a staffed responsibility rather than a dashboard someone occasionally checks.
Data scientists may investigate performance changes, while ML engineers and platform teams maintain serving and data pipelines. Cybersecurity, product leaders, and business operations may need defined responsibilities for access, acceptable use, and operational response.
Before launch, the team should establish a performance baseline, alert thresholds, retraining triggers, rollback procedures, and incident documentation. Retraining shouldn't be automatic approval: a replacement model still needs evaluation before it takes over.
Periodic review should also revisit whether the original decision remains worth supporting. Success means maintaining a useful, accountable decision process, not preserving a model indefinitely.
As one staffing option for these projects, nexus IT group connects employers with specialized technology professionals through contract staffing, direct placement, and executive search. Employers building predictive-modeling capabilities can visit the firm to discuss data science, machine-learning engineering, and production ownership requirements before opening a search.
